
Matt Pocock@mattpocockuk 코드 가독성에 대한 기존의 전제를 다시 생각해 봐야 합니다. 사람은 에이전트에 비해 많은 양의 텍스트를 이해하는 속도가 꽤 느립니다. 그래서 예전에는 사람이 무슨 일이 일어나는지 효율적으로 파악할 수 있도록 가독성을 높이는 것이 중요했습니다. 이제 가독성에서 중요한 것은 다음 두 가지입니다. 1. 필요할 때 사람이 코드를 들여다보고 이해할 수 있는가? 2. 코드가 그 코드를 설명하는 사람이 쓰는 것과 같은 도메인 언어를 사용하는가? 첫 번째는 동작을 관찰하고 중요한 PR을 가끔 점검할 때 도움이 됩니다. 두 번째는 에이전트가 여러분의 말을 코드 변경으로 옮기는 데 도움이 됩니다. 다시 말해, 이제 가독성은 필수 조건이라기보다 있으면 좋은 요소입니다. 에이전트가 코드를 ‘읽는’ 방식은 다릅니다. 좋은 에이전트는 코드가 어떻게 동작하는지에 관한 데이터를 수집하는 데 집중합니다. 코드를 이리저리 살펴보고, 일부를 실행해 보기도 합니다. 그러니 에이전트에게 ‘가독성’이란 사실상 ‘검증 가능성’입니다. 코드를 직접 다뤄 보며 동작을 확인하기가 얼마나 쉬운지가 중요합니다. 이런 상황을 생각해 봅시다. - 코드베이스에 온갖 복잡한 성능 최적화 기법을 사용하는 거대한 모듈이 있습니다. - 테스트 커버리지는 100%입니다. 유능한 사람이라도 그 모듈을 편하게 수정하려면 한두 시간은 필요할 겁니다. 에이전트에게는 그런 적응 시간이 필요하지 않습니다. 테스트로 검증하고 조금 살펴보면 바로 작업할 수 있습니다. 핵심은 다음과 같습니다. - 모듈이나 코드베이스를 평가할 때, 코드가 얼마나 읽기 쉬운지만 생각하지 마세요. - 대신 얼마나 검증하기 쉬운지 생각하세요. - 각 모듈을 독립적으로 테스트하고 검증할 수 있도록 코드베이스를 설계하세요. - 성능을 위해 가독성을 조금 희생하는 것은 괜찮습니다. - 순환 복잡도와 함수 크기는 에이전트에게 중요하지 않습니다.
We need to reconsider our priors on code readability. Humans, compared to agents, are pretty slow at understanding large quantities of text. So in the old days, readability was important so the human could efficiently grok what was going on. So readability now comes down to: 1. Can a human, if needed, jump in and understand the code 2. Does the code use the same domain language as the human describing the code? 1 helps with observability and the occasional spot checks you need to do on important PR's. 2 helps the agent translate the words you use into code changes. In other words, readability is now a nicety, not a necessity. The way agents 'read' code is different - good agents are all about gathering data about how the code works. They'll prod around with it, execute parts of it. So 'readability' to agents really means 'verifiability'. How easy it is to mess about with that code to see it working. Let's take this scenario: - You have a huge module in your codebase that uses all sorts of complex performance tricks - It has 100% test coverage A talented human would need an hour or two to get comfortable working in that module. An agent needs zero time. They verify it with the tests, poke about a bit, and they're good to go. The takeaways: - When judging a module (or a codebase), don't think about how easy the code is to read - Instead, think about how easy it is to verify - Design your codebase so modules can be tested and verified independently - Feel free to sacrifice a bit of readability for performance - Cyclomatic complexity and function size don't matter to agents

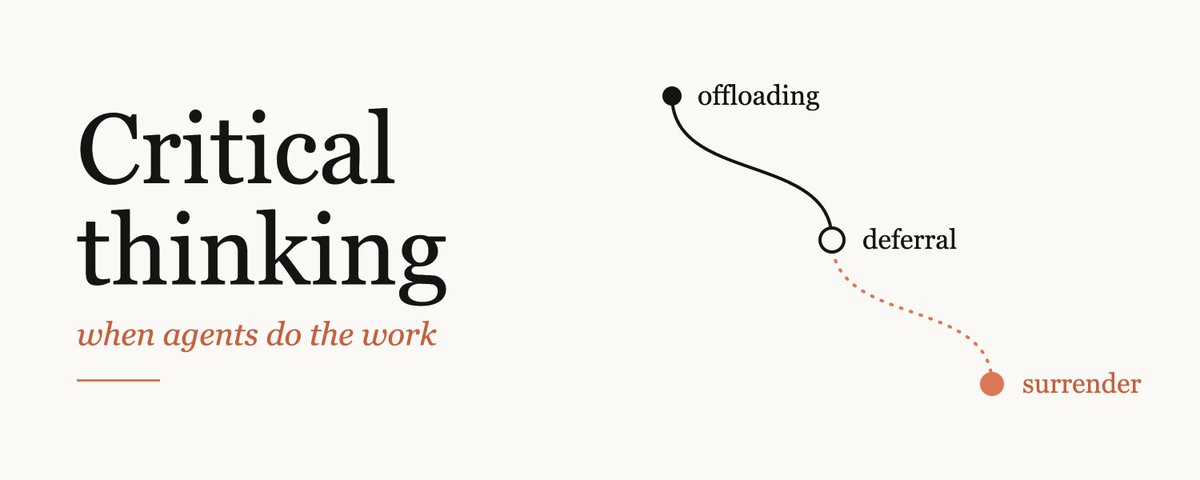
Addy Osmani@addyosmani 에이전트가 일을 할 때 필요한 비판적 사고 예전에는 비판적 사고란 새로운 정보를 겸손한 호기심과 적절한 의심으로 대하고, 다양한 관점을 받아들인 뒤 자기 의견을 세우는 것이라고 배웠습니다. 지금도 맞는 말입니다. 하지만 제 업무의 상당 부분을 에이전트로 처리하게 되면서, 일상에서 비판적으로 생각하도록 저를 떠미는 일이 점점 사라지고 있습니다. 여러 세션을 병렬로 돌리고 모델이 더 좋아질 거라 기대하며 에이전트 중심의 업무 방식에 완전히 뛰어든 엔지니어와 제품 담당자들에게 말하고 싶습니다. 저도 이 도구들을 정말 좋아합니다. 에이전트 활용을 줄이자고 이 글을 쓰는 것이 아닙니다. 제 목표는 무엇이든 에이전트에게 맡기기 쉬워진 세상에서 여러분이 비판적 사고를 유지하도록 돕는 것입니다. 과거에는 질문과 답 사이의 시간에 인지적 처리와 미적 판단의 상당 부분이 이루어졌습니다. 이제 그 간격은 몇 초에 불과합니다. 에이전트 중심의 업무 방식을 많이 사용할수록 이것은 더 어려워집니다. 다만 사람들이 예상했던 방식과는 다릅니다. 모델이 좋아질수록 명백한 오류의 비율은 줄어듭니다. 많은 결과물, 어쩌면 대부분의 결과물은 잘 쓰여 있고 대체로 맞지만, 다시 살펴봐야겠다는 생각을 들게 하지는 않습니다. 에이전트를 여러 개 동시에 돌려도 결과물을 보는 여러분의 눈은 여전히 한 쌍뿐입니다. 일상에 비판적 사고를 의도적으로 끼워 넣어야 합니다. 기본 상태에서는 아무것도 여러분을 대신해 그렇게 해 주지 않기 때문입니다. 스스로 이를 바로잡기 어려운 이유 중 하나는 에이전트와 일하는 경험이 즐겁기 때문입니다. 바쁜 하루에 빠르고 기분 좋고 대체로 맞는 답을 받는 것은 반가운 일이지만, 바로 그렇기 때문에 경계를 풀기도 쉽습니다. 위임, 판단 유보, 사고의 포기 사람들과 이 주제를 이야기할 때 저는 이를 하나의 연속선으로 설명합니다. 맨 위에는 인지적 위임이 있습니다. 작업은 AI에게 맡기되 결과에 대한 주인의식은 유지하는 것입니다. 저도 하루 종일 이렇게 합니다. 여러분도 그래야 합니다. 중간에는 판단을 도구에 맡기는 단계가 있습니다. 도구의 출력이 곧 자신의 새로운 입력이 되고, 결과를 더 이상 가설로 취급하지 않는 상태입니다. 맨 아래에는 인지적 항복이 있습니다. AI의 출력이 조용히 내 생각이 되고, 확인할 필요조차 느끼지 않는 상태입니다. ‘인지적 항복’은 와튼스쿨의 Steven Shaw와 Gideon Nave가 만든 용어입니다. 제가 관찰한 현상을 정확히 설명합니다. 신뢰가 커지거나 게을러질수록 사람들은 이 연속선 아래로 내려갑니다. 각 단계의 변화가 점진적이고 합리적으로 보이기 때문에 그 전환을 알아차리는 경우는 드뭅니다. 방금 답은 꼼꼼히 읽었으니 다음 답은 훑어봅니다. 그다음 답은 뼈대만 봅니다. 그러다 누군가 특정 줄에 관해 물으면 에이전트의 도움을 받아도 설명하지 못합니다. 이것이 인지적 항복입니다. 인지적 부채는 이렇게 쌓입니다. 시스템에 대한 머릿속 모델을 적용하려다가 그런 모델이 없다는 사실을 깨달을 때 비로소 드러나는 경우가 많습니다. Margaret-Anne Storey는 팀이 공유하는 시스템 이론에 대한 이해가 약해지는 형태로 이 현상이 나타난다고 썼습니다. 저도 코드에서의 같은 현상을 ‘이해 부채’라고 쓴 적이 있습니다. Jeremy Twei가 만든 용어입니다. 당장은 전혀 보이지 않습니다. 코드베이스는 깔끔하고 테스트도 통과합니다. 시스템을 바꿔야 하는 순간, 이제는 아무도 이를 이해하지 못한다는 사실을 깨닫기 전까지는 드러나지 않습니다. 전략 문서나 명세의 목차만 읽고 승인했을 때도 마찬가지입니다. 분명히 해 두자면, 불가능한 일을 요구하는 것은 아닙니다. 규모가 큰 현대적인 코드베이스 전체를 머릿속에 유지하는 것은 불가능합니다. Claude Code 팀은 필요할 때 이해를 다시 구축한다고 공개적으로 이야기했습니다. 어떤 부분을 이해해야 하면 전체 모델을 머리에 담아 두는 대신 Claude에게 그 부분을 설명해 달라고 요청하는 것입니다. 앞서 썼듯 이런 종류의 부채는 많은 엔지니어가 예상하는 것보다 회복하기 쉽습니다. 필요할 때 해당 부분에 대한 이해를 재구성할 수 있다면 전체 모델을 계속 유지할 필요는 없습니다. 자신이 무엇을 이해하지 못하고 있는지만 알면 됩니다. 잘못되어도 영향이 작은 일은 전부 위임해도 괜찮습니다. 하지만 에이전트의 도움을 받아서도 답을 설명할 수 없다면, 결과에 대한 주인의식을 넘겨준 것입니다. 이것이 언제나 문제인 것도 아닙니다. 얼마 전 강의를 녹화하면서 평점이 비슷한 호텔 세 곳 중 녹화 장소로 쓸 곳을 골라야 했습니다. 리뷰를 일일이 읽을 시간이 없어 AI에게 결정을 맡겼습니다. 결과는 좋았고, 다시 해도 똑같이 할 것입니다. 하지만 돈을 어떻게 투자할지, 아이들의 진로에 어떤 조언을 할지, 업무에서 무엇을 만들지, 어떤 변경이 어떤 사용자에게 영향을 미치는지, 배포해도 안전한지 결정할 때는 그렇게 하지 않을 겁니다. 틀렸을 때의 비용이 작은 일은 넘기되, 그 결과를 다른 사람이 감당해야 하는 일에서는 판단의 근거를 직접 붙잡고 있어야 합니다. 스스로에게 던지는 질문들 내 생각이 무엇인지 모르겠을 때 저는 보통 기본적인 질문 목록으로 돌아갔습니다. 올바른 문제를 풀고 있다는 것을 어떻게 알 수 있을까? 올바른 방식으로 풀고 있다는 것은? 내 결론을 뒷받침하는 증거가 있을까? 끝났다는 것은 어떻게 알까? 대개는 누가, 무엇을, 어디서, 왜, 언제, 어떻게에 관한 질문입니다. 적어 놓으면 우스울 만큼 어린아이 같은 질문이지만, 평소 놓쳤을 범주까지 생각하게 해 줍니다. 요즘은 이 과정을 모두 건너뛰고 에이전트에게 뭘 해야 할 것 같은지 물어보기가 너무 쉽습니다. 다음은 제가 지금 스스로에게 묻는 질문들입니다. 묻기 전에 가설을 세웠는가? 사소하지 않은 일을 에이전트에게 맡기기 전에는 답이 무엇일지 제 생각을 적습니다. 머릿속으로만 해도 좋습니다. 서툰 추측이어도 괜찮습니다. 새로운 정보를 보고 생각을 바꾸는 것은 언제나 좋습니다. 하지만 잘 쓰인 답변을 읽고 나면 다른 가능성을 상상하기 어려워집니다. 아무런 실마리도 없다면 Thariq Shihipar가 말하는 ‘사각지대 점검’을 요청하세요. 자신이 아는 것을 모델에게 주고, 자신이 모른다는 것조차 모르는 부분을 찾아 달라고 하는 것입니다. 내가 생각하도록 돕기를 원하는가, 아니면 내 생각을 대신 맡기려는가? 어느 쪽이든 괜찮습니다. 다만 지금 어느 쪽을 하고 있는지 알아야 합니다. 이 답이 틀리려면 무엇이 사실이어야 하는가? 그런 다음 직접 확인하세요. 모델이 스스로 매긴 확신의 정도보다 실제로 수행할 수 있는 테스트가 훨씬 가치 있습니다. 그러니 테스트를 마련하세요. 다른 각도에서 반론을 들어 보았는가? 정답이 열려 있는 주제에 강한 입장을 취했다면, 둘 이상의 모델에게 반대 입장을 주장하게 한 다음 결과를 검토하고 제 의견을 정합니다. 시간은 더 들지만 그 주제를 훨씬 잘 이해하게 됩니다. 이 결과물을 유지보수할 사람 앞에서도 여기에 걸겠는가? 코드뿐 아니라 여러분이 전달하는 모든 결과물에 해당합니다. 저는 이것이 책임 있게 설명할 수 있는지의 기준이라고 생각합니다. 더 이상 연습하지 않게 된 것은 무엇인가? 일상적인 디버깅의 일부일 수도 있습니다. 어느 정도는 손에서 놓아도 괜찮지만, 의도적으로 결정하고 싶습니다. 습관으로서의 검증 요즘 제가 검증에 관해 많이 쓰는 이유는 병목이 코딩에서 ‘내가 맞다는 것을 확신하는 일’로 옮겨갔다고 믿기 때문입니다. 에이전트에게 자신이 하는 일을 검증할 수단을 주면, 엔드투엔드 테스트든 속성 기반 테스트든 실제 앱 조작이든, 여러분이 들여다보기도 전에 변경하고 검증 테스트를 돌리고 결과를 읽고 다시 시도할 수 있습니다. Boris Cherny는 이를 ‘Claude에게 자신의 작업을 검증할 방법을 주라’고 표현합니다. 저는 이것이 좋은 결과를 얻는 가장 중요한 요소 중 하나라고 믿습니다. 모든 줄을 읽기보다 이런 검증 루프를 만들고 증거를 검토하게 되는 것입니다. 검증마저 넘겨줄 수도 있습니다. ‘내 결론을 뒷받침하는 증거가 있는가?’가 ‘검사가 초록색으로 바뀌었는가?’로 변합니다. 에이전트 덕분에 테스트 작성 비용이 아주 낮아져 초록색 표시를 자주 보게 되지만, 고장 난 기능을 잡아내지 못하는 테스트도 통과할 수 있습니다. 테스트에 기능과 같은 실수가 들어 있으면 통과합니다. 그리고 초록색 표시는 단 하나의 속성만 말해 줍니다. 그것이 모든 것을 확인한다고 착각하기 너무 쉽습니다. 검사가 통과하면 무엇을 입증했는지 물어보세요. 그런 다음 무엇을 입증하지 못했는지 물어보세요. ‘검증됐다’의 의미를 미리 정하세요. 일이 끝난 뒤에는 어떤 결과든 합리화하게 됩니다. 에이전트 작업의 결승선은 테스트 통과, 스크린샷, 로그나 추적 기록처럼 구체적인 것이어야 합니다. 그래야 작업의 완료 기준이 사실에 근거하며, ‘끝난 것 같다’는 느낌에 따라 해석하거나 포기할 여지가 없어집니다. 에이전트에게 완료 알림을 받으면 요약을 보기 전에 먼저 실행한 명령과 그 결과를 확인하세요. Claude Code는 새로운 컨텍스트의 서브에이전트를 통해 자신의 작업을 상식 수준에서 비평할 수도 있습니다. 생각날 때만이 아니라 매번 실행되도록 검증 루프에 넣어 두는 것이 좋습니다. 저도 끝에 여전히 ‘놓친 것이 있나요?’라고 묻습니다. 우습게 들릴 수 있지만, 최상위 모델로 복잡한 기능을 구현하고 결과를 검토한 뒤 이 질문을 하면 두세 가지를 더 찾아오는 경우가 아주 많습니다. 그래서 항상 묻습니다. 물론 이 모든 것을 매번 할 필요는 없습니다. 언제 깊이 들어가야 하는지 아는 것도 능력입니다. Claude Code 팀의 코드 리뷰 방식에 관해 함께 쓴 글에서 제가 가장 좋아하는 경험칙은 이렇습니다. ‘검사가 무엇을 놓칠 수 있는지 말할 수 없다면, 간단한 승인 대신 제대로 된 리뷰를 요청하라.’ 코드 외의 작업에도 적용됩니다. 에이전트가 고객 통화 50건을 종합하거나 경쟁사 분석을 했다면 원본 문서 몇 개를 확인해 요약이 정확한지 보세요. 추천의 근거가 되는 숫자가 있다면 계산이 맞는지 확인하세요. 에이전트 덕분에 검증 체계를 갖추는 비용은 낮아졌습니다. 여러분에게 어려운 일은 좋은 검증이 어떤 모습인지 아는 것입니다. 생성된 결과물에 실제로 주의를 기울이기 에이전트가 600줄짜리 PR을 올렸다고 합시다. 구조를 대략 살펴봅니다. 모든 줄을 읽지는 않습니다. 변수 이름은 그럴듯하고 테스트도 통과하니 승인합니다. 하지만 중간 어딘가에는 트랜잭션 경계에서의 미묘한 순서 변경이나, 생각해 본 적 없는 예외 상황에서 뒤집힌 기본값이 숨어 있습니다. 리뷰는 했다고 할 수 있겠지만, 이미 찾으리라 예상했던 것만 본 셈입니다. 코드를 작성하는 것과 리뷰하는 것은 다른 능력이며, 어느 순간부터 리뷰는 형식적인 승인으로 변합니다. 그러니 AI가 작성했다는 사실을 잊고 변경 사항을 읽은 다음, 변경 사항 너머에서 에이전트가 무엇을 결정했는지 보세요. 긴 세션 동안 에이전트는 기본값, 범위에서 제외할 일, 요구사항 두 개가 충돌할 때 어느 쪽을 재해석할지 등 작은 결정을 많이 내립니다. 모든 것이 잘됐다는 요약에서는 이런 결정이 보이지 않습니다. 그러니 어떤 결정과 가정을 했는지 나열해 달라고 하세요. 그런 다음 자신에게 퀴즈를 내세요. 몇 줄을 무작위로 골라 이 줄은 왜 이렇지, 저 줄은 어떻지 물어보세요. 문서라면 닫고 핵심 주장을 기억으로 적어 보세요. 긴 세션에서 제가 좋아하는 습관을 가진 사람들도 있습니다. Claude에게 변경 보고서를 쓰고 맨 아래에 퀴즈를 붙이게 합니다. 규칙은 ‘퀴즈를 완벽히 통과해야 머지한다’입니다. 출시하는 것을 설명하고 옹호할 수 있을 만큼 이해하세요. 언젠가는 누군가 물을 수 있으니까요. 에이전트는 여러분의 주의력을 지켜줄 수도 있습니다. 예를 들어 제 오픈소스 프로젝트에는 PR이 많이 올라옵니다. 저는 무엇이 들어오고 있는지, 무엇이 지침에 어긋나는지, 어디에 제 주의가 필요한지 판단하는 데 에이전트를 사용합니다. 이런 판단을 에이전트에게 전적으로 맡기지는 않지만, 집중할 지점의 범위를 좁혀줄 수는 있습니다. 그러면 그 변경이 올바른 문제를 올바른 방식으로 풀고 있는지 제가 직접 생각할 수 있습니다. 그리고 물량의 문제가 있습니다. 이 점에 관해서는 자신에게 솔직해야 합니다. 저는 이를 ‘오케스트레이션 세금’이라고 부른 적이 있습니다. 에이전트가 생성하는 것과 여러분이 자기 이름을 걸어도 좋다고 느끼는 것 사이의 격차입니다. 완료된 작업이 검토 속도보다 빨리 쌓인다면 이 문제를 해결하기 전에는 세션을 하나 더 늘려도 도움이 되지 않습니다. 검사 체계를 강화해 직접 볼 양을 줄이거나, 속도를 늦추세요. 자신이 책임질 수 있는 양보다 많이 생산하고 있다면, 이제는 리뷰하는 것이 아닙니다. 잘되기를 바라고 있는 것입니다. 좋은 입력에서 좋은 출력으로 사람의 머릿속 모델은 여전히 필요합니다. 다만 중간이 아니라 시작과 끝에 관여합니다. 작업 설명과 컨텍스트를 준비하는 앞단, 그리고 결과물을 검토하는 뒷단에 에너지를 쓰게 됩니다. 그래서 좋은 입력이 출력의 품질에 매우 중요하며, 저는 좋은 프롬프트를 쓰는 것을 비판적 사고의 한 능력으로 봅니다. 예전에는 불명확한 요청을 하면 누군가 이의를 제기했고, 그 덕분에 ‘잠깐, 나도 이걸 아직 정리하지 않았네’ 하고 깨닫기도 했습니다. 에이전트는 그 지점에서 여러분을 멈춰 세우지 않는 경우가 많습니다. 빠뜨린 부분을 채우고, 그 바탕의 생각은 여전히 흐릿한데도 끝난 것처럼 보이는 결과를 건넵니다. 저는 이를 ‘의도 부채’라고 쓴 적이 있습니다. 직접 쓰지 않은 결과물 안에 암묵적인 목표, 제약, 근거가 들어 있을 수 있다는 뜻입니다. 다른 종류의 부채와 달리 이것은 다른 사람이 대신 해결해 줄 수 없습니다. 의도는 여러분에게서 나와야 합니다. 프롬프트에는 여러분이 문제를 얼마나 이해했는지가 드러납니다. 명확하게 표현할 수 없다면, 자신의 머릿속에서도 명확하지 않을 수 있습니다. 도움을 요청하기 전에 자신의 말로 작업 요청서를 쓰세요. 독자나 사용자, 범위에서 제외할 일, 완료의 정의를 적으세요. 두 번째 수정 요청으로도 원하는 결과를 얻지 못했다면, 조금씩 고치는 것을 멈추고 프롬프트를 다시 쓰세요. 이 과정도 에이전트의 도움을 받을 수 있습니다. 저는 Andy Clark이 AI 시스템에 위임하는 것과 협업하는 것을 구분한 방식을 좋아합니다. 협업에서는 서로를 증폭하는 선순환이 생깁니다. 프롬프트가 출력을 날카롭게 하고, 출력이 다음 프롬프트와 문제에 대한 이해를 더 날카롭게 합니다. 불명확하다면 무엇을 이해하지 못했는지 에이전트가 여러분을 인터뷰하게 하세요. 세션이 끝날 때 자신의 머릿속 모델이 더 정교해졌다면 성공의 신호입니다. 입력에도 주의하세요. 각 에이전트가 이전 에이전트의 요약을 그대로 컨텍스트에 넣다 보면, 어느새 세 번째 에이전트는 원본 문서를 읽지도 않은 상태가 되기 쉽습니다. 출력에 대한 자신의 기준도 필요합니다. 저는 여러 창작 분야에서 AI를 실험해 봤지만, 대부분은 제 기준에 미치지 못해 공개하지 않았습니다. 이제는 모든 것이 보기 좋게 정리되고 확신에 차서 나오므로, 겉모습의 완성도는 더 이상 유용한 신호가 아닙니다. AI 덕분에 제작 속도가 빨라졌을 수는 있지만, 제 이름을 붙여도 좋다고 느끼지 않는 결과물은 내놓지 않습니다. 기준에 미치지 못했다면 그 이유를 공유 설정, 훅, 테스트에 기록해서 같은 일이 다시 일어나지 않게 하세요. 그렇게 취향과 판단력이 쌓입니다. 무엇이 기준을 통과하지 못했는지 이유를 기록하는 것 자체도 좋은 연습입니다. ‘하지만 모델이 나보다 이 일을 더 잘하게 될 텐데’ 주변의 많은 사람처럼 이 분야의 미래를 낙관한다면, 몇 절 전부터 이런 생각을 했을지도 모릅니다. 1~2년 뒤면 모델이 내가 잡아낼 수 있는 문제를 잡아낼 텐데, 굳이 이 능력을 유지할 필요가 있을까? 문제를 발견하는 능력에 관해서는 상당 부분 맞을 수도 있습니다. 저도 점점 더 많은 문제 탐지를 에이전트에게 맡기자고 주장해 왔습니다. 하지만 여전히 중요하다고 생각하는 이유가 있습니다. 결국 출시되는 것에는 누군가 책임을 져야 합니다. AI가 얼마나 도왔든 사람이 책임져야 합니다. 특정 작업에서 에이전트를 얼마나 믿을지는 그 자체로 판단의 문제입니다. 모델이 틀리는 지점은 계속 바뀌기 때문에, 제대로 감을 유지하려면 결과물을 검토해야 합니다. Anthropic이 자사 엔지니어와 연구자를 조사한 연구에서도 이를 ‘감독의 역설’이라는 함정으로 지적합니다. ‘Claude를 감독하려면 AI 과용으로 약해질 수 있는 바로 그 코딩 능력이 필요하다’는 것입니다. 저에게 가장 중요하며, 모델이 더 좋아져도 대신 해결해 주지 못하는 질문들이 있습니다. 무엇을 만들고 있는가, 왜 만들 가치가 있는가, 누구에게 영향을 미치는가, 무엇을 희생할 의향이 있는가? 이 질문에는 여러분이 답해야 합니다. 에이전트가 답을 찾아가는 데 도움이 될 수 있고 저도 그러기를 바라지만, 결국 여러분의 질문입니다. 작업과 검토의 상당 부분을 넘길 수는 있어도, 최종 책임까지 넘길 수는 없습니다. 일상에서 실천할 것들 이 모든 것을 엄격하게 할 필요는 없습니다. 자신의 업무 방식에 맞는 것을 골라 넣으면 됩니다. 일주일에 한 번은 에이전트 없이 코드를 조금 작성하거나, 하는 법을 잊으면 곤란할 실제 작업 하나를 해 보세요. 저는 이를 감각을 점검하는 연습이라고 불렀지만, 도덕적인 의미는 아닙니다. 한 달에 한 번은 더 이상 하지 않게 된 일을 적고, 그중 무엇은 하지 않아도 괜찮은지 정하세요. 예전 블로그 글에서 던진 질문은 여전히 유효합니다. AI가 없다면 여러분은 얼마나 막막할까요? 이해 수준을 넘어서는 것이 있다면 배우세요. 글을 쓰다가 처음 보는 표현을 만나면, 검색해서 한 줄 설명을 넣을 수도 있습니다. 저는 조금 더 조사해서 제대로 이해한 뒤 어디에 들어맞는지 살펴보는 편을 선호합니다. 기계를 제대로 점검하는 것도 실제 노동입니다. 그렇지 않은 척하면 결국 팀은 그 일을 하지 않게 됩니다. 공짜가 아니니 일정에 하나의 항목으로 잡아 두어야 실제로 하게 됩니다. 쓰지 않는 능력은 사라집니다. 아마 예상하는 것보다 빠를 겁니다. 놓치고 싶지 않은 능력은 계속 사용하세요. 기억해 둘 것들 의도적으로 하세요. 에이전트는 여러분에게 퀴즈를 내고, 인터뷰하고, 증거를 보여줄 수 있습니다. 다만 그렇게 하도록 설정해야 합니다. 그러니 설정하세요. 그 연속선에서 자신이 어디에 있는지 솔직해지세요. 에이전트의 도움을 받아도 답을 설명할 수 없다면, 이미 사고를 넘겨준 것입니다. 가설을 세우세요. 서툴러도 좋으니 묻기 전에 세우세요. 초록색 표시는 한 가지를 뜻합니다. 무엇을 검사했나요? 무엇은 검사하지 않았나요? 증거를 찾으세요. 요약보다 먼저 무엇을 실행했고 어떤 결과가 나왔는지 읽으세요. 어떤 결정을 내렸는지 알기 위해 읽으세요. 에이전트가 여러분 대신 무엇을 결정했나요? 프롬프트를 다듬으세요. 요청을 어떻게 쓰는지에 여러분이 문제를 얼마나 이해했는지가 드러납니다. 기준을 세우고 지키세요. 자신의 이름을 걸 수 없다면 내놓지 마세요. 중요한 능력을 직접 사용하면서 계속 참여하세요. 한 가지 해 볼 만한 방법이 있습니다. 묻기 전에 어떤 일이 일어날 것 같은지 적고, 에이전트의 작업이 끝난 뒤에는 확인하지 않은 것 한 가지를 적으세요. 이것이 결과물을 읽는 방식을 바꾸는지 알려주세요. 독립적으로 생각하세요. 더 나은 질문을 하세요. 결과에 책임을 지세요. x.com/i/article/2116367635365695488
Critical thinking when agents do the work Back in the day, critical thinking was taught as approaching new info with humble curiosity and a healthy dose of skepticism - take in different views, form your own opinion. Still true, but increasingly, nothing in my day-to-day forces critical thinking on me now that so much of my work runs through agents. For the engineers and product people who have fully bought into agentic workflows (running multiple sessions in parallel and expecting the models to improve), I'm here to say: I'm a big fan of these tools. I'm not writing this to advocate for less agentic workflows. My goal is to help you maintain critical thinking in a world where it's easy to offload anything to an agent. In the past, most of our cognitive and aesthetic processing happened in the space between question and answer. That space is now measured in seconds. The more you use agentic workflows, the more difficult it becomes (though not in the way I think people expected): as the models improve, the percentage of obvious errors is lower. Many (most?) outputs will be well-written and mostly correct, but they won't demand a second look. Even if you are running many agents at a time, you still only have one pair of eyes on the outputs. You have to build critical thinking into your day, because by default nothing will do it for you. Part of the reason it's hard to self-correct for this is that agentic workflows are pleasant. Getting fast, pleasant, often-correct answers is refreshing in a busy day, but that's also why it's easy to relax your vigilance. Offloading, deferral and surrender When discussing this with people, I describe it as a spectrum: At the top: cognitive offloading, the act of delegating tasks to the AI, but maintaining ownership of the result. I do this all day. You should, too. In the middle: deferral, where the output of the tool becomes your new input; the result has ceased to be a hypothesis. At the bottom: cognitive surrender - the AI's output quietly becomes your own, you feel no need to check it. Cognitive surrender is a term coined by Steven Shaw and Gideon Nave at Wharton. It fits neatly what I've been seeing: as trust (or laziness) increases, people drift down the spectrum. The transition is rarely observed, because the steps are each gradual and seem reasonable. You read the last answer well, so you skim the next one. You just scan the skeleton of the one after that. Then you get asked about a line and can't explain it, even with your agent's help. That's cognitive surrender. It's how cognitive debt accumulates. It's usually discovered when you try to apply a mental model of the system and it doesn't exist. Margaret-Anne Storey has written about how this shows up in teams as an eroding understanding of a shared system theory. I've written about the code equivalent, comprehension debt (a term coined by Jeremy Twei). In the moment, it's completely invisible. The codebase looks pristine and the tests pass. It doesn't become obvious until you have to make a change to the system and realize that nobody understands it anymore. The same applies when you've read the table of contents of a strategy doc or spec and signed off on it. To be clear, I'm not advocating for the impossible. It's impossible to maintain the full mental model of a large modern codebase. The Claude Code team has said publicly that they rebuild understanding on demand: when they need to understand a part, they ask Claude to explain that slice, rather than holding the full model in their heads. As I've written about before, this sort of debt is more recoverable than most engineers expect. You don't need to maintain the full model as long as you can rebuild it locally as needed. You just need to know what you don't have. Where the stakes are low, feel free to delegate entirely. When you can't explain the answer to a question, even by way of your agent, you've ceded ownership. This isn't always a problem, either. Just recently, I was recording a course and had to select one out of three similarly-rated hotels to use as a recording location. I didn't have time to manually review all the reviews, so I delegated the decision to an AI. It worked, and I'd do the same thing again. However, I wouldn't do that when deciding how to invest our money, how to advise our kids on their careers, or at work: what we should build, what changes affect what users, whether it's safe to ship. Take the handoff where being wrong is cheap, keep the reasoning where others will have to deal with the consequences. The questions I ask myself When I didn't know what I thought, I'd usually go back to a basic list of questions like these: How do I know that I'm working on the right problem? How do I know that I'm solving it the right way? Is there evidence that supports my conclusion? How do I know that I'm finished? Most times, this is just who, what, where, why, when and how. When written out, it looks absurdly child-like, but it forces you to think in terms of categories that you'd otherwise ignore. These days, it's too easy to simply skip all of this and ask your agent what it thinks you should do. These are the new versions of these questions that I ask myself now. Did I formulate a hypothesis before asking? Before I run an agent on any non-trivial task, I write down, even just in my head, what I think the answer might be. It's OK if it's a bad guess. You're always welcome to change your mind in light of new information. Once you've read a well-written response, though, it's hard to imagine any other possibility. If you have no guidance whatsoever, ask for what Thariq Shihipar calls a blind spot pass: give the model what you know and have it find your unknown unknowns. Am I asking it to help me think or to offload thinking from me? Both are OK, as long as you know which one you're doing. What would have to be true for this to be wrong? Then go find out. A model's self-assessment of confidence is much less valuable than an actual test you can perform, so give it one. Have I heard the counter argument from a different angle? When I've taken a hard stance on something that's somewhat open-ended, I'll ask more than one model to argue the opposite side, then review the output and form my own opinion. This takes longer, but I end up knowing much more about the subject. Would I bet on this in front of the person who has to maintain it? This applies to code and to anything else that you're delivering. I believe that this is the bar for answerability. What am I no longer practicing? Maybe it's some of the routine debugging. I'm OK with letting some of that go, but I want it to be intentional. Verification as a habit I've been writing a lot about verification lately because I believe that the bottleneck has shifted from coding to being sure you're right. When you give an agent the means to verify what it's doing, whether that be by way of end-to-end tests, property tests, or by way of actual app interactions, it can make a change, run the verification test, read the output, and attempt again all before you've looked at anything. This is what Boris Cherny calls "give Claude a way to verify its work" and I believe that this is one of the most critical components of achieving great results. Rather than reading every line, you'll be building these loops and reviewing the evidence. You can also surrender verification. "Is there evidence that supports my conclusion?" becomes "Did the check turn green?" Agents make it so cheap to create tests that you'll see a lot of green, and you could have a passing test that doesn't catch a broken feature. If the test is written with the same mistake as the feature, it'll pass. And a green check only conveys one property. It's too easy to imagine it covers everything. When a check goes green, ask what it proved. Then ask what it didn't. Define "verified" upfront, because post-facto, you'll rationalize any outcome. The finish line for agent work should be something tangible: a test passing, a screenshot, a log or trace. This ensures that the criteria for finishing the work is factual, and not up for interpretation (and surrender) based on something like "it looks like it's done." When you receive a finish notification from an agent, before you look at the summary, first review the code snippet of the command executed and its output. Claude Code can also self-critique (via a subagent in a fresh context) its own work as a sanity check, and it's worth baking that into the loop so it runs every time, not just when you remember. I still ask at the end "Did I miss anything?" That sounds silly, but so often, when I finish some complex feature work using a frontier model, look at it, review it, and then ask, "Did I miss anything?" It will then come back with two or three more things. That's why I always ask. None of this needs to be the norm, of course; knowing when to go deep is a skill. My favorite rule of thumb from our write-up on how the Claude Code team does code review is: "If you can't say what the checks would miss, ask for a real review rather than a quick approval." This applies beyond code as well. If an agent has synthesized fifty customer calls for you, or a competitive analysis, check a couple of the source documents to make sure the summary is accurate. Check a number that your recommendation depends on to make sure it's being calculated correctly. Agents have made verification cheap to set up. What's difficult for you is knowing what good verification looks like. Actually paying attention to what's generated Say an agent gives you a 600-line PR. You roughly look at the structure. You don't read every line. The variable names look reasonable and the tests pass, so you approve it. But somewhere in the middle there's a subtle ordering change in a transaction boundary, or a flipped default on an edge case you never thought about. You did review it, I guess, but only for what you already knew you'd find. Writing code and reviewing it are different skills, and there's a point where reviewing turns into rubber stamping. So read the diff as if the AI didn't write it, and then look past the diff at what the agent decided. Over a long session it makes a lot of small decisions for you: the defaults, what's out of scope, which requirement it reinterprets when two of them clash. You won't see any of that in a summary that says everything went well, so ask it to list the decisions and assumptions it made. Then quiz yourself. Pick a few lines at random and ask, what about this line? What about that one? For a document, close it and try to write out the main argument from memory. Some have a habit I like for long sessions: have Claude write a report on the change, and then give you a quiz at the bottom, where the rule is "I only merge after I pass the quiz perfectly." Understand what you're shipping well enough to defend it. Because at some point, someone could ask. Agents can also guard your attention. For example, I have an open source project that receives a lot of pull requests. I'll use agents to help determine what's incoming, what's contrary to our guidelines, and where my attention is likely required. I rarely let the agents self-determine this, but they can narrow it down to where I should focus my attention, and then I can actually think about whether these changes are solving the right problem in the right way. Then there's volume, and you have to be honest with yourself about it. I've called this the orchestration tax. It's the gap between what your agents generate and what you'd feel comfortable putting your name on. If finished work is piling up faster than you can get through it, another session won't help until you've fixed that: tighten the checks so less of it needs you, or slow down. When you're producing more than you can stand behind, you're no longer reviewing. You're hoping. Quality in, quality out The human mental model is still involved, but instead of in the middle, it's at the front and end. You're putting your energy into the front-end of the task description and context, as well as the back-end of reviewing the output. This is why good input is so important to the quality of output, and I view good prompting as a critical thinking skill. Historically, if you made a non-specific request, someone would challenge it, and you might realize, "Oh wait, I actually didn't figure this out." An agent often won't stop you there. It fills in what you left out and hands back something that looks done, even though the idea behind it is still fuzzy. I've written about this as intent debt, the implicit goals, constraints and rationale that may exist in artifacts you didn't write. Unlike other kinds of debt, nobody else can fix this one for you. The intent has to come from you. Your prompt is a reflection of your understanding of the problem, and if you can't express it clearly, it may not be clear in your own mind. Write your own request brief in your own words before you ask for help. Describe the audience, out-of-scope items, and the definition of done. When your second round of corrections hasn't got you there, stop tweaking and rewrite your prompt. You can have the agent help you with this too. I like the distinction Andy Clark makes between delegating to an AI system and collaborating with it. In the latter case, you're in a virtuous cycle of mutual amplification: your prompts sharpen your output, sharpen your next prompt and sharpen your mental model of the problem. If it's not clear, ask the agent to interview you about what it doesn't understand. If you close the session having refined your own mental model, that's a sign of success. Also be careful about the input. It's easy for each agent to just pass the previous agent's summary into its context, and before long the third agent hasn't read the original document. You also need your own standards for output. I've played around with AI in lots of different creative mediums, and most of it never gets shown because it doesn't meet my standards. Things are all coming out nicely formatted and confident, so polish is no longer a useful signal. AI may have made it faster to produce, but if I wouldn't feel comfortable attributing the output to myself, I won't output it. When something doesn't meet your standards, note why in shared config, a hook or a test so that it doesn't happen again. That's how taste compounds, and noting why something didn't make the cut is good practice on its own. "But the models will be better at this than me" If you're as bullish on the future of this space as many people around me are, you've probably had this thought for a couple of sections. In a year or two, the model will be able to detect what I'd be able to detect, so why bother maintaining the skill? You may be right on a lot of that detection, and I've been arguing for increasingly pushing detection to agents myself. But here's why I think it still matters: at the end of the day, someone is responsible for what ships. Regardless of how much AI helped, a human has to take responsibility. The question of how much to trust an agent for any given task is itself a judgment call. Part of staying calibrated is reviewing the work, because what the models get wrong keeps changing. Anthropic's own research on its engineers and researchers calls out the trap as the paradox of supervision: "supervising Claude requires the very coding skills that may atrophy from AI overuse." These are some of the things that matter most to me and that a better model won't solve: what are you building, why is it worth it, who does it impact and what are you willing to sacrifice? Those are all questions you need to answer. An agent can be helpful in working them through, and I would like it to be, but ultimately they're still yours. You may offload the work and much of the auditing, but not the accountability. Practices for the everyday You don't need to do all this rigorously. Just plug in what works for your workflow. Once a week, write a bit of code without an agent, or do one real thing that would suck if you forgot how to do it. (I've called this a calibration exercise, but I don't mean it as a moral one.) Once a month, write down what you've stopped doing and decide which of those you're okay not doing. One question from an old blog post of mine remains as valid as ever: How lost would you be if AI didn't exist? If something is above your comprehension, go learn it. If I'm writing and I run into a phrase I haven't seen before, I could Google a one-line explanation and include it. I prefer to do a little research to properly understand it, so I can see where it fits. Checking the machine properly is real work, and pretending otherwise is how teams end up not doing it. It isn't free, so schedule it as a line item and you'll actually get it done. Skills that you stop exercising are going to go away, and probably faster than you might guess. Keep doing the ones you're not willing to let go. What to bring with you Be intentional. An agent can quiz you, interview you and show you its evidence, but only if you set that up. So set it up. Be honest about your place on the spectrum. If you can't explain the answer, even with an agent's help, you've surrendered it. Have a hypothesis. Formulate one before asking, even if it's bad. A green check means one thing. What did it check? What did it not check? Look for evidence. Read what it ran and what it returned before reading the summary. Read to know what decisions it made. What did it decide for you? Craft your prompt. How you write what you prompt shows how much you understood the problem. Set a bar, and stick to it. If you wouldn't put your name on it, it doesn't go out. Keep yourself in the game by manually applying the skills that matter. One thing you could do: Before you ask, write down what you think will happen, and after the agent is done, write down one thing it didn't check. Let me know if that changes the way you read the output. Think independently. Ask better questions. Take responsibility for the outcome. x.com/i/article/2116367635365695488

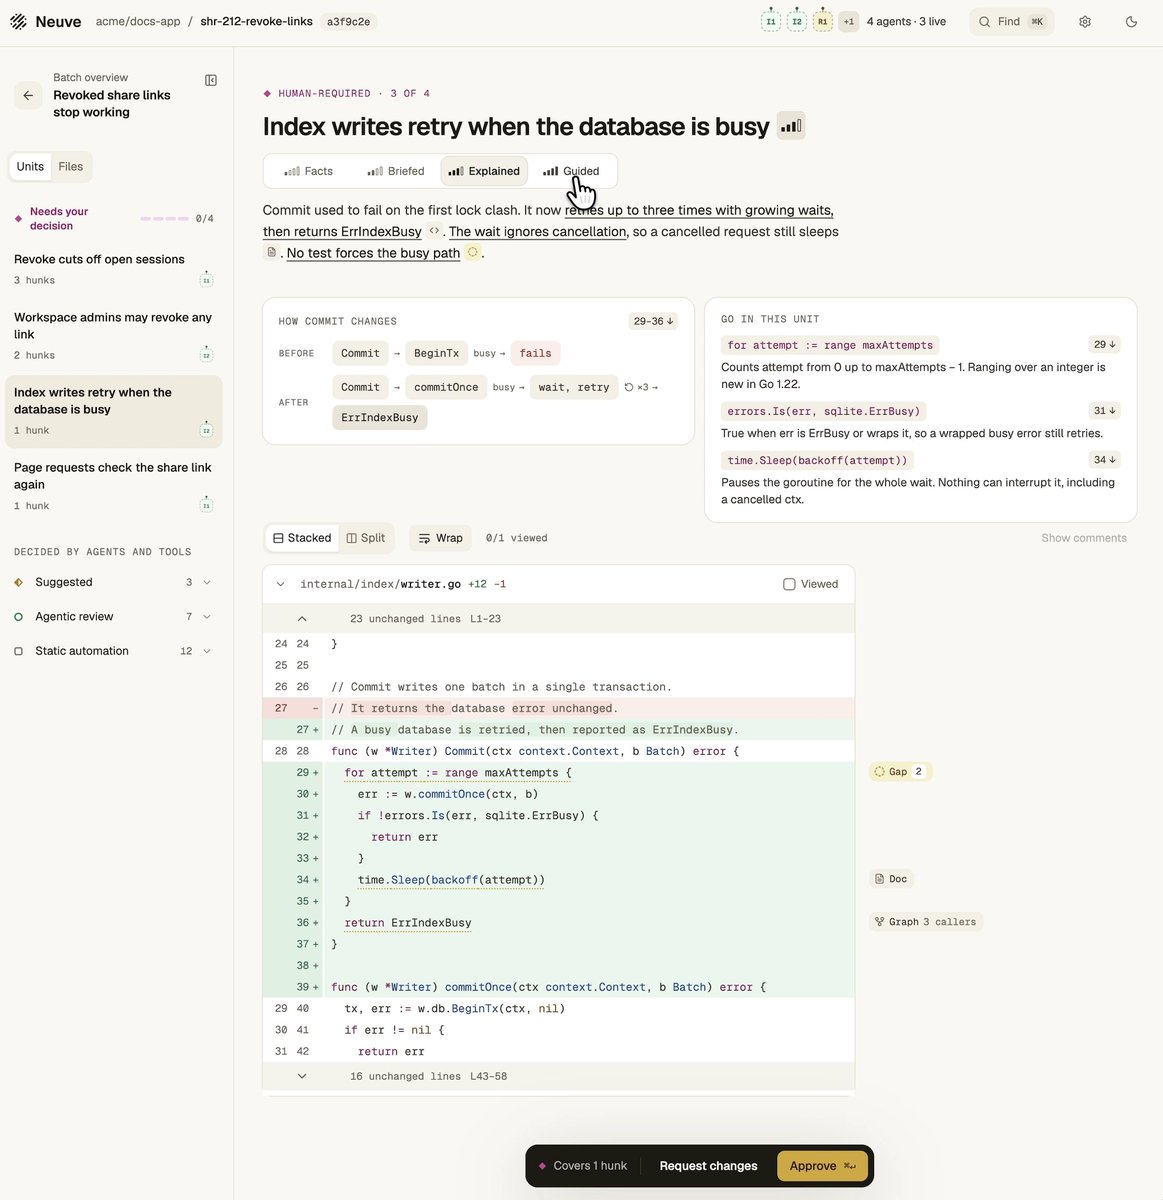
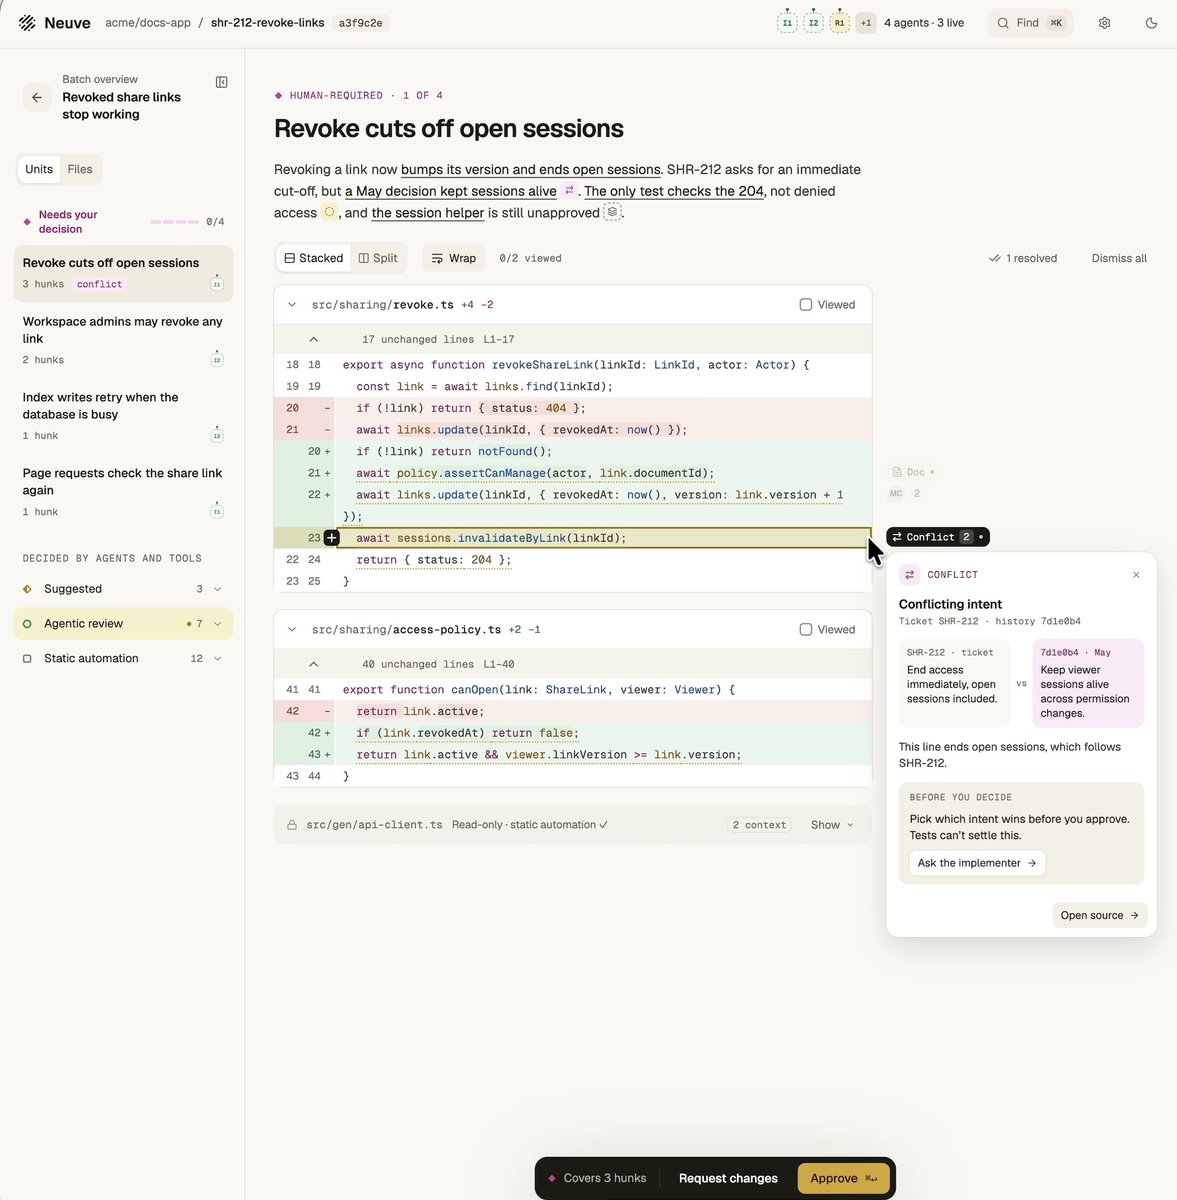
Vinicius Dallacqua@WebTwitr 이제 코드 리뷰는 프로세스의 문제가 아닙니다. 제게는 데이터 문제에 더 가까워 보입니다. 그러니 코드 리뷰를 다루고, 이를 위한 도구를 만들고, 생각하는 접근 방식도 바뀌어야 합니다. 코드 리뷰는 이제 데이터 문제입니다 거의 1년 동안 반복해서 개선하고 만들어 온 것에 관해 이제 좀 더 이야기할 때가 된 것 같습니다. QA를 위한 에이전트를 만들기 시작했을 때, QA가 비교적 쉽게 성과를 낼 수 있는 분야이기는 하지만 팀이 겪는 가장 큰 마찰 지점은 아니라는 사실을 깨닫는 데 오래 걸리지 않았습니다. 올해 초부터 모든 팀이 체감하기 시작한 핵심 문제는 코드 리뷰였습니다. 회사마다 이 문제에 대응하는 전략이나 나름의 대처 방식이 있습니다. 에이전트에게 요약을 만들게 하기도 하고, 우선순위를 분류하는 절차를 두기도 하며, 그 밖에도 ‘그건 에이전트에게 맡기면 된다’는 식의 여러 접근이 있습니다. 이런 접근에 반드시 반대하는 것은 아니지만, 제 생각에는 몇 가지를 놓치고 있습니다. 1. 검증이 과정의 자연스러운 일부가 되지 못합니다. 도중에 빠지거나, 검증을 자연스럽게 드러내고 다룰 자리가 없습니다. 2. 변경 사항을 이해하기가 쉽지 않은 경우가 많습니다. 3. 우선순위를 분류하고 자동화를 설계하는 기준으로 PR 자체가 적절한 변경 단위가 아닌 경우가 많습니다. 그 이유는 @addyosmani가 여기서 아주 잘 설명했습니다. 이제 PR 자체는 적절한 기본 단위가 아닙니다. 코드는 더 이상 지식의 문제가 아니라 데이터에 기반한 문제입니다. 하지만 최종 결과물에도 더 작게 나누어 살펴볼 여지가 있다고 생각합니다. 모든 코드의 중요도가 같지는 않습니다 따라서 브랜치 전체를 하나의 변경 단위로 다루는 것은 더 이상 적절한 방식이 아닙니다. 여기에는 토큰 사용의 경제성, 검증, 정확성 문제가 함께 얽혀 있습니다. 코드베이스의 각 부분은 영향 범위, 과거의 맥락(장애, 자주 실행되는 경로 등), 복잡도 변화 양상, 구조적 중요도에 따라 중요도가 다를 수 있습니다. 자동화(CI), 에이전트 리뷰, 사람의 리뷰 중 무엇이 필요한지 판단할 때 이 모든 차원을 고려해야 합니다. 인지적으로 우리는 모두 파산 상태입니다 리뷰 봇이 그토록 매력적인 이유 중 하나는 우리가 더 이상 이해하지 못하는 코드베이스에 대한 책임의 부담을 덜어주기를 바라기 때문입니다. 하지만 봇은 우리가 여전히 그 코드에 책임이 있고, 여전히 이해해야 한다는 사실을 놓칩니다. 모든 줄을 하나씩 이해해야 한다는 뜻은 아닙니다. 더 높은 수준에서, 변경 사항들의 체계로 이해해야 한다는 뜻입니다. 우리의 세심한 선별과 관리 없이는 제품이 잘 성장할 수 없습니다. 따라서 기존의 코드 리뷰를 대체할 다음 방식은 코드를 평가하는 것이 아니라 변경 사항을 검증하는 데 초점을 맞춰야 합니다. 다른 데이터 문제와 마찬가지로, 이 데이터 문제의 해법도 적절한 시각화 도구를 사용하는 것입니다. 변경과 맥락 이제는 변경을 맥락과 연결하는 시스템이 필요합니다. 사람뿐 아니라 에이전트에게도 그렇습니다. 모델은 작업에 필요한 정보를 스스로 찾아내는 데 매우 능숙해졌지만, 더 큰 목표나 범위 안에서는 예상치 못한 부분을 놓치거나, 최악의 경우 방향을 잃기도 합니다. 우리는 이제 ‘코드는 쓰고 버리면 된다’는 사고방식에 끌립니다. 하지만 저는 여전히 낭비라고 느낍니다. 에이전트는 자신의 지능과 적절한 도구를 함께 활용해, 변경에 필요한 범위를 독립적으로 찾아내고 검토할 수 있어야 합니다. 이것은 시작에 불과합니다. 외부에 선보일 준비를 마치기 전 마지막 개선 작업을 진행하면서, 빠르면 다음 주부터 초기 피드백을 모으기 시작할 계획입니다. 지금도 다른 사람들이 기존 코드 리뷰 도구를 사용할 때 어떤 어려움, 마찰, 막히는 지점을 겪는지 궁금합니다. x.com/i/article/2017338533850042368
The code review is no longer a process problem, to me it more closely resembles a data problem. So our approach to how we treat, build for and reason about it also needs to change. Code review is now a data problem Maybe it's time I start sharing more about something I've been iterating and building for almost a year now. When I've started working on building agents for QA, it did not take too much time for me to realize that, althought a great low-hanging fruit, QA is not the main friction point for teams. The main issue that all teams since earlier this year started to feel was code reviews. And for any company out there there's a strategy, or coping mechanisms, to deal with this issue. Sometimes it involves throwing agents at it to bring you digests, sometimes there's a triaging process and many other forms of "there's an agent for that". Although I don't necessarily disagree with such approaches, for me it misses some marks: 1. Validation is not a natural part of the process, as in it gets lost or does not have a natural surface area 2. Understanding the changes is often not an easy task 3. The PR itself is often not the right unit of change to triage and base automations on The reason for all of that is very well described by @addyosmani here. The PR itself is not the right primitive anymore. Code is not a knowledge issue, now it is a data driven problem. But even on the final work I believe there's room for deconstruction. Not all code has the same importance So treating the whole branch as a unit of change is no longer the right way to handle it. It's a mix of a tokenomics issue, validation and also correctness issue. Different parts of the codebase can have different importance, based on blast-radius, historical context (outages, hot-paths, etc), complexity curves or structural importance. All of which are different dymensions to consider when assessing between automation (CI), agentic or human reviews to be necessary. We are all bankrupt, cognitively One of the reasons that reviewer bots are so good is because we want them to take away the burden of responsibility on a codebase that we no longer understand. But they miss the fact that we are still responsible for them and still should understand them. No on a line-by-line basis but on a higher level, a system of changes. Our products cannot thrive without our careful curation. So the next thing to surplant code reviews as we knew it is no longer on assessing the code, but verifying the changes. So the solution to this data problem is, as any data problem before it, to use the right visualization tools. Change and context We are now in need of a system that attributes change to context. This is not just for us but for agents too. Though models have become very capable of sourcing their needs to perform a task, often they can be blindside or in worst cases get lost in the larger goal or scope. We are now tempted to 'code is throwaway' mentality, but I feel like that is still wasteful. Agents should be able to use their inteligence alongside the right set of tools to help them independently source and review scope for changes. This is only the beginning, I'm planning to start colecting early feedback on this as early as next week as I proceed with my last 'hill climbs' before this thing is ready for external attention. But I'm now also curious to hear from different people their struggles and friction points and sticking points when using code reviewing tools out there. x.com/i/article/2017338533850042368


Thariq@trq212 지금 정말 이상한 일이 벌어지고 있어요. 기술을 아는 사람들은 자신의 기술이 이제 쓸모없어졌다며 슬퍼하고, 기술을 모르는 사람들은 에이전트를 더 잘 활용할 수 있도록 자신에게 기술 지식이 더 있었으면 하고 간절히 바라고 있어요.
very weird thing happening rn technical people are sad, they think their skills are now useless non-technical people are desperately wishing they were more technical so they could use agents better

lauren@poteto 지난달 PR 2,500개를 프로덕션에 배포한 방법을 공유합니다. 원래 런던에서 열린 Cursor Compile에서 발표하려던 내용이에요. Grok @Bot Galaxy에서 라이브 스트리밍을 하느라 참석하지 못해서, 여기 X에 무료로 공개합니다! 제가 말이 느린 편이니 2배속으로 보세요.
here's how i shipped 2,500 PRs last month to production this was originally supposed to be for Cursor Compile in London. i couldn't make it since i was livestreaming for Grok @Bot Galaxy so i'm making it available for free here on X! watch it on 2x speed, i talk slowly
 X에서 영상 보기


